What is a tagged PDF? Definition and accessibility
A tagged PDF has an invisible structure layer that tells assistive technology what each piece of content means. That layer can define headings, paragraphs, lists, tables, figures, links, and reading order. But automatic tagging is only a starting point. A tagged file still needs verification against WCAG 2.1 AA and PDF/UA.
In this guide, you'll see how tags work, where they fail, and how teams verify large document libraries without treating a passing checker score as the whole answer.
What a tagged PDF is
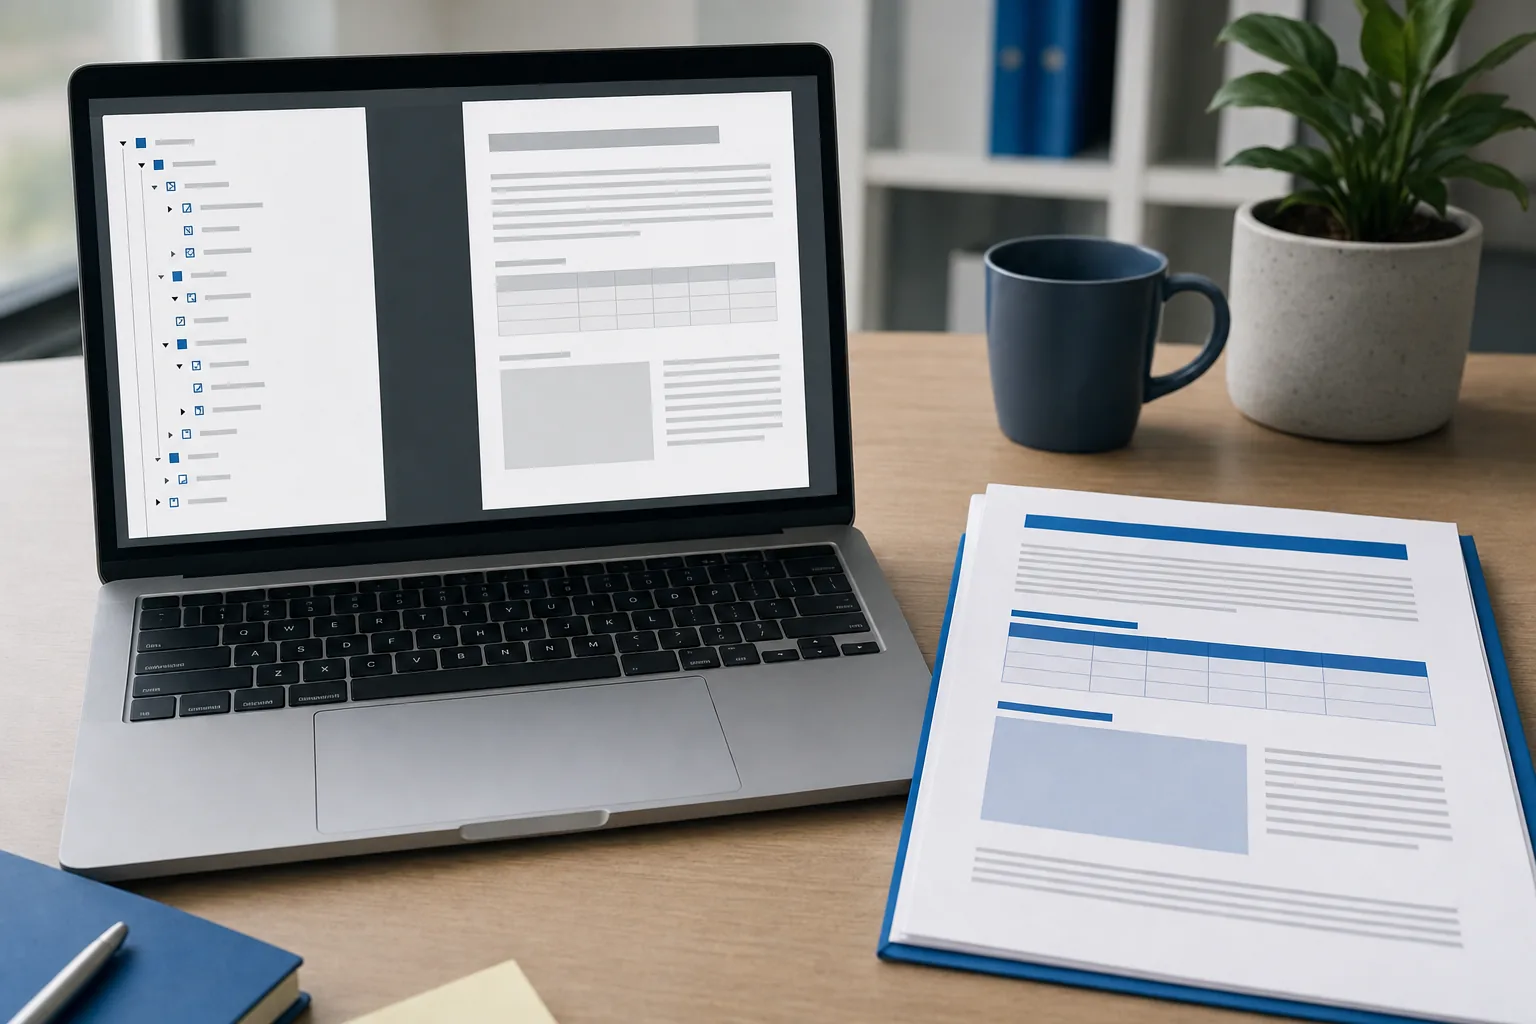
A tagged PDF is a PDF with a logical structure tree. The tree gives meaning to content that may look clear on screen but appear as a loose pile of text and graphics to a screen reader.
Think of a printed report. A sighted reader can spot the title by its size, find a heading by its position, and know that text beside a chart belongs to that chart. A screen reader needs more than visual position. It needs the file to state, “this is a heading,” “this is a paragraph,” or “this image has this alternative text.”
Tags carry that information. Common tags include:
- Document: the top-level container for the structure tree.
- Heading: a heading with a level such as H1 or H2.
- P: ordinary paragraph text.
- L, LI, and LBody: a list, its list items, and the body of each item.
- Table: a table container with rows, headers, and data cells.
- Figure: an image or other visual object that may need alternate text.
- Link: a link with descriptive text and an associated link object.
The result is a machine-readable outline. A screen-reader user can move by heading, hear list structure, understand table headers, and skip content marked as an artifact. An artifact is a visual object with no reading meaning, such as a decorative line or repeated background shape.
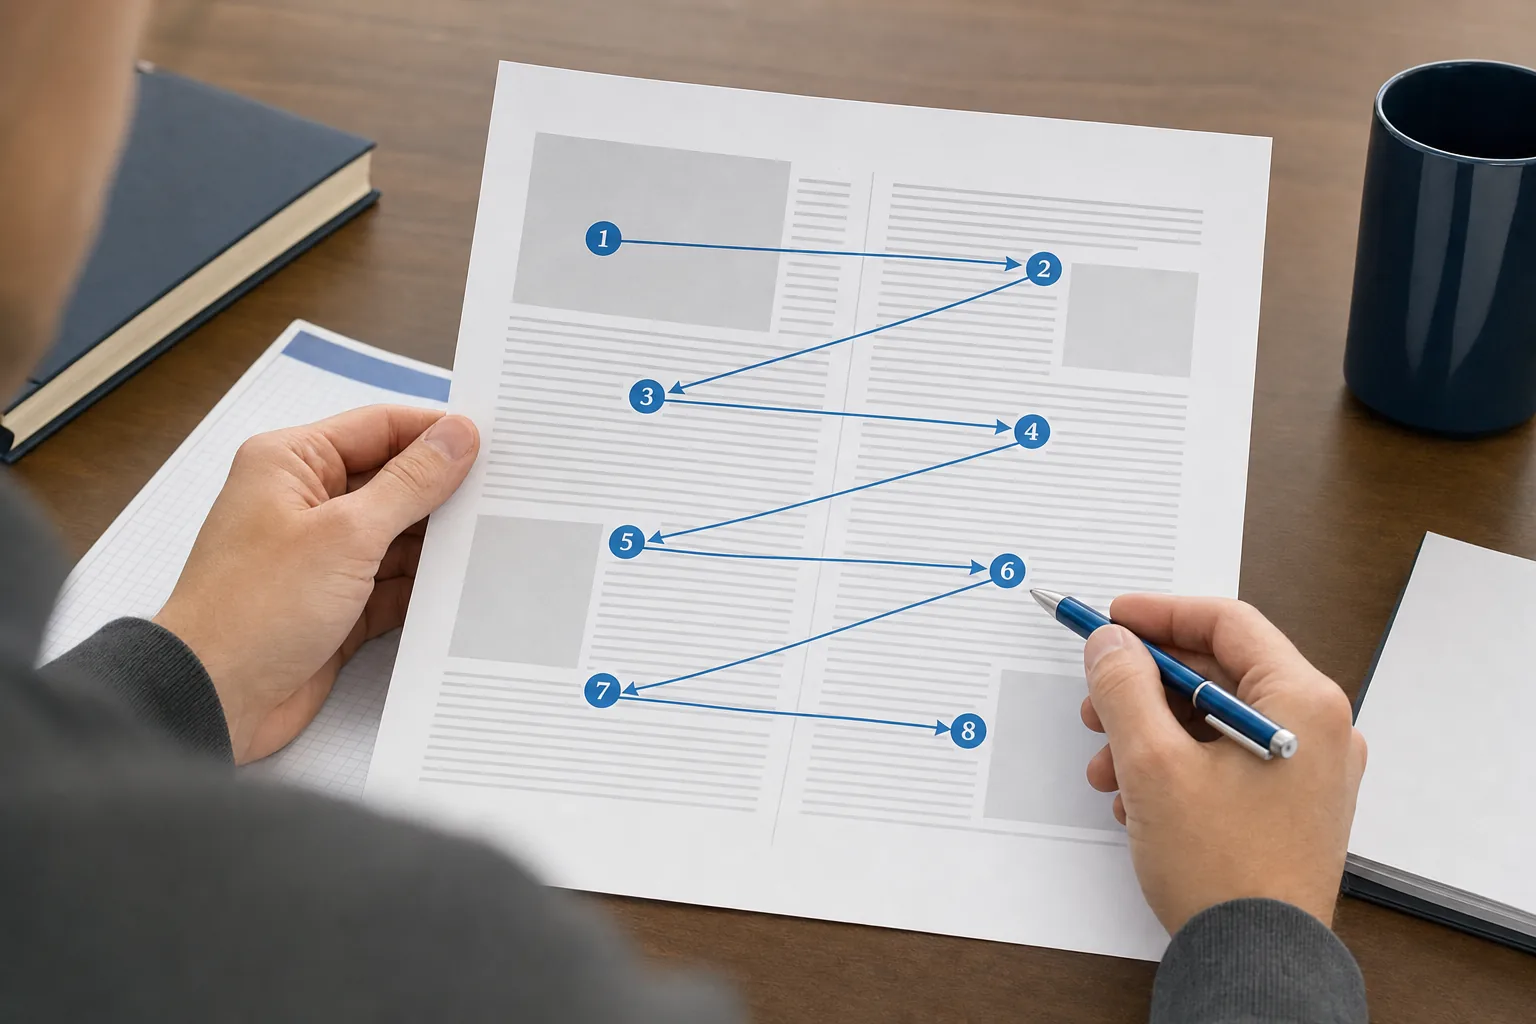
A tagged PDF is not automatically an accessible PDF. Tags can be missing, placed in the wrong order, or assigned to the wrong content. A heading may be tagged as a paragraph. A chart may have alt text that says only “image.” A two-column page may read down the left column, then jump to the footer, then return to the right column.
Automatic tagging can result in inaccurate tags, missed elements, and a misordered reading order, so an auto-tagged file is not compliant by itself.
WCAG 2.1 AA and PDF/UA also answer different questions. WCAG focuses on the outcome for users across digital content. PDF/UA, which is ISO 14289, gives PDF-specific rules for the file's internal structure. A useful explanation of that difference appears in university accessibility guidance comparing WCAG and PDF/UA.
Use both ideas when you assess a file. WCAG 2.1 AA is the version ADA Title II references. PDF/UA adds the technical detail needed to inspect the PDF itself. A tag tree helps with both, but it is only one part of the work.
How tags create a document structure
Tags create a document structure by turning visual parts of a PDF into a hierarchy. For someone asking what a tagged PDF is, this hierarchy is the key idea: the file tells a reader what content is, not only where it sits.
The first tag should be a Document tag. Other tags sit below it, either directly or inside a grouping container. A simple report might look like this:
Document H1: Annual report P: Opening paragraph H2: Services P: Description of services L LI LBody: First item LI LBody: Second item Table TR TH: Category TH: Amount TR TD: Total TD: ValueThis tree is not meant to copy the visual page. It represents the order and role of the content. A large blue line above a section may be decorative. A bold sentence may be a heading, or it may be emphasized body text. The tag must match the meaning a reader would get from the page.
Heading levels need care. A document can have an H1 followed by H2 sections and H3 subsections. The exact pattern depends on the document, but the hierarchy should make sense when read as an outline. A heading that skips levels may not always break the file, yet it can make navigation harder and may signal that the source structure was never planned.
Paragraph tags handle normal body text. List tags preserve grouping. Without list structure, a screen reader may read each line as separate text and never tell the user that the lines form one list. That changes meaning. “Step one,” “step two,” and “step three” should sound like members of the same group.
Tables require even more care. The tag tree needs to show rows and cells, while the PDF also needs a clear relationship between header cells and data cells. A table that looks tidy may still read poorly if the headers are missing or the cells arrive in the wrong sequence.
Figures need a decision, not just a tag. If an image carries meaning, the figure needs useful alternate text. If it is decorative, it can be marked as an artifact. The wrong choice causes trouble in either direction. A missing description hides information. A long description of a decorative flourish adds noise.
Links have structure too. Descriptive link text gives the user a useful destination before activation. “Read the policy” tells more than “click here.” The link tag also needs to connect the visible text with the interactive link object.
Automatic tagging can suggest this tree, but it sees layout clues rather than intent. It may treat a running header as a heading, split one paragraph into several, or place a caption before the figure it describes. That is why the most common advice in accessibility checklists has a built-in warning: run the automatic tool, then inspect its work.
In a small file, an operator can open the Tags panel and correct the tree by hand. In a large archive, that same action repeats across thousands of pages. The issue becomes process control. Does the same layout get the same structure each time, or does quality change with the person assigned to page 4 and page 400,000?
For a deeper look at software categories, the PDF tagging software comparison separates desktop editing from automated remediation and verification. That distinction helps you choose a workflow instead of buying a checker and calling the job complete.
Why reading order matters
Reading order tells a screen reader how to move through a tagged PDF. It is often the part that exposes a weak tag tree because a page can have every visible object tagged and still read like nonsense.
On a single-column page, the order seems simple. The title comes first, followed by the body. A page with two columns, sidebars, pull quotes, footnotes, or a table is different. The visual layout guides the eye, while the tag sequence guides assistive technology.
Imagine a public notice with a heading at the top, two columns of instructions, and a shaded warning box between them. A bad sequence might read the first line of the left column, jump to the warning box, move to the footer, and then return to the rest of the instructions. Every object is present. The message is still hard to follow.
The reading order is the order of tags shown in the structure tree. It should follow a sensible path through the content. That path may differ from the exact position of objects on the page, especially when a design uses sidebars or floating boxes.
Reading order also affects keyboard use. If a file contains links or fields, the sequence should support the task the user came to complete. A form that starts with a confirmation button, skips a required field, and then returns to the first question creates a poor experience even if every field has a label.
Tables show the same problem in another form. A screen reader needs to move through the table in a predictable pattern and identify the header context for each cell. If the structure follows the visual placement of isolated text blocks instead, the user may hear values without knowing what they mean.
Review the order with more than a checker. A machine test can find structural defects, but it may not know whether a sidebar belongs before or after the main paragraph. A human has to compare the tag sequence with the page's meaning.
At Accessibility On Demand™, the Review Modal puts reading-order visualization beside the full tag tree. That lets a reviewer see the sequence rather than guess from a list of tags. The same view supports alt-text editing, so a reviewer can confirm that the page reads as a coherent document.
Scanned PDFs add another layer. A scan begins as an image. OCR creates a text layer, but searchable text alone does not give the page headings, lists, table relationships, or correct reading order. OCR must be followed by structure work.
Reading order is also where automatic tagging's limits become clear. A source file may contain text boxes in an arbitrary creation order. The PDF can look perfect to a sighted reader while its internal order follows the sequence in which a designer drew objects. A repair process has to infer the intended sequence and then give a person a way to check it.
When you test, read several pages aloud with a screen reader. Pick a normal page, a dense page, a page with a table, and a page with a callout. A short sample reveals more than a single cover page because layout errors often appear only when the design changes.
Which PDF elements need tags and alternate text
A tagged PDF needs a decision for every meaningful element. The question is not “does this object exist on the page?” It is “what should a user understand, and how should assistive technology deliver it?”
Headings and paragraphs
Headings need levels that show the document outline. The main title is usually the top heading. Section headings sit below it. A paragraph tag identifies normal text, so a bold paragraph does not become a heading simply because it uses a larger font.
Check the outline without looking at the page. If the headings alone don't describe the document's sections, the tag structure needs work. This is a fast way to catch a page that looks polished but has weak semantics.
Lists and tables
Lists need list structure. The List tag groups the items, while List Item and List Body tags preserve the relationship between the bullet or number and its text.
Tables need row and cell structure. Header cells need to be identified as headers, not ordinary data. Watch for layout tables that only position content. If a table carries no data relationship, it may need a different structure or artifact treatment.
Figures and alternate text
A meaningful figure needs alternate text that communicates its purpose. A chart should state the useful trend or comparison, not merely say “chart.” A photo may need a short description of the event or person shown. A decorative line should not receive a made-up description.
Alternate text should fit the surrounding text. If the paragraph already explains a chart, the figure description can avoid repeating the same words. If the image contains information not found elsewhere, the description needs to carry that information.
Links and form fields
Links need descriptive text. Form fields need labels that identify what the user should enter. Their tab order should follow the task. A visible label near a field is helpful, but the field also needs a programmatic name that assistive technology can find.
Fillable forms are the hardest PDF type to remediate because labels, tooltips, tab order, and field structure interact. Accessibility On Demand™ handles forms through the Review Modal today, where a person confirms field labels and tab order. A fully automated forms pipeline is expected in Q3 2026.
Color and contrast sit outside the tag tree. A tagged PDF can still use text that is hard to see. Remediation adds semantic structure; it does not change the visual appearance, including contrast, fonts, or layout. If the source design has a contrast problem, tagging alone won't fix it.
That boundary explains why a score should be treated as the floor, not the proof. The file needs technical checks plus a human review of meaning and use.
Tagged PDFs, standards, and accessibility checks
A tagged PDF should be checked against both the content standard and the PDF standard. WCAG 2.1 AA is the version ADA Title II references, while PDF/UA supplies PDF-specific rules for tags, structure, and internal behavior.
PDF/UA uses machine-checkable conditions defined through the Matterhorn Protocol. A validator can inspect many of those conditions. It can report missing tags, broken structure, metadata problems, and other file-level issues.
PAC, the PDF Accessibility Checker, is maintained by an industry standards organization and available through a specialized accessibility software provider. The current release is PAC 2026. Its report helps locate errors, and its screen-reader preview supports a visual and listening review.
A PAC score is computed, not asserted: checks passed divided by checks run, per standard. Every score needs its method in the same sentence because a score without a named method is hard to interpret.
Automated checks are strong at repeatable rules. They are weaker at questions of intent. A checker may confirm that an image has alt text, but it may not know whether the description is useful. It may confirm a tag exists, but it may not know whether the tag matches the visible meaning.
That is why a sound test has several parts:
- Run a machine checker against PDF/UA and relevant WCAG criteria.
- Inspect the tag tree for hierarchy, missing content, and wrong roles.
- Review reading order on complex pages.
- Check figures and alternate text for meaning.
- Use a screen reader to test headings, links, tables, and forms.
- Record the file, checker result, review status, and any source limits.
veraPDF is another open-source PDF/UA validator and is useful in cross-platform or CI workflows. Different validators can disagree on edge cases, so some teams run multiple validators together. The point is not to collect scores. It is to understand what each test covers and what remains a human judgment.
Accessibility On Demand™ runs every processed document through an automated PDF checker API and provides a Compliance Score Certificate. We are benchmarking 97%+ average compliance scores across production volume, verified through the Axes4 PAC Checker API. That score is a floor, not proof of a perfect document.
For organizations accountable under ADA Title II, Section 508, or Section 504, keep the evidence with the output. An auditor may ask how a file was tested, which standard was used, and who reviewed exceptions. A tagged file without that record leaves an avoidable gap.
How tagged PDFs are created, repaired, and verified at scale
Tagged PDFs are created through authoring, repair, and verification. The right path depends on how many files you have, how varied they are, and whether someone on your team can inspect each result.
Start with the source
The cheapest page to remediate is the page authored with structure already in place. Use real heading styles in the source document. Give images useful descriptions. Build tables with header relationships. Keep link text meaningful.
This helps future files, but it doesn't solve an old archive. Existing PDFs may have no tags, a broken text layer, or layout objects arranged in the wrong internal order. They need repair.
Choose the workflow shape
A desktop editor fits a small number of files where a trained operator needs detailed control. The operator can inspect each tag, fix the reading order, and save the result. This is a sensible choice for a handful of complex documents.
A specialist remediation suite fits high-scrutiny documents that need hands-on review. The tradeoff is labor. Manual remediation of a complex page commonly runs 15–30+ minutes. Specialist firms commonly charge $5–$25+ per page, with complex fillable forms reaching $100+ per page. The cost scales linearly with volume.
Automation changes the shape of a large backlog. Accessibility On Demand™ uses deterministic processing for structural work with a correct answer, such as tags, reading order, and table markup. That processing behaves identically on page 4 and page 400,000.
Generative AI is used only where judgment is needed, such as drafting alt text. Its output can be checked in the Review Modal. This split matters. It keeps repeatable structure work from drifting while leaving uncertain meaning open to review.
Match the service level to risk
Accessibility On Demand™ publishes three service levels:
- Standard (Level 1), $0.30/page: for text-based PDFs, internal archives, and high-volume backlogs needing a clean baseline. It includes OCR on scans, automated tagging, logical reading order, basic image alt text, and a Compliance Score Certificate on every document.
- Enhanced (Level 2), $1.80/page: for public-facing documents. It adds contextual alt text for images and charts, advanced form-field tagging, and configurable bookmarks. Level 2 targets a 95%+ WCAG 2.1 AA Compliance Score, verified by the PAC (Axes4) checker. If a document doesn't clear 95%, you're not charged for it, with rare source-document exceptions.
- Expert Review (Level 3), $12/page: for legally sensitive documents where governance requires human sign-off. Expert Review targets a 99% Compliance Score, verified by the PAC (Axes4) checker, with full WCAG 2.1 AA plus PDF/UA and human verification.
The choice should follow the document's risk, not a desire for the largest number. An internal archive may need a defensible baseline. A public form may need human confirmation. A document of record may need a review trail that names the reviewer and records corrections.
Verify the output
Verification starts with the checker report. Then inspect the document itself. Open the tag tree. Review reading order. Test headings and links with a screen reader. Check a table with multiple rows. For forms, tab through every field and confirm that each label makes sense. For a structured testing sequence, follow this step-by-step PDF accessibility testing guide.
At scale, sample selection matters. Include different templates, page types, scan quality, tables, charts, and forms. A clean first page proves very little if the archive contains hundreds of layouts.
We processed 600,000 pages in May 2026, including a 50,000-page single-day run for one customer. That proves throughput for that production volume, not perfect output for every source. A compliance score remains the floor, not the proof, and source defects can still limit what remediation can change.
Our platform is the wrong fit when you have only a few documents a year, need a desktop editor, or must run an SDK on your own infrastructure. In those cases, a trained operator or an on-premises development tool may fit better. For a large mixed backlog, API access is available for high-volume integrations.
FAQ: tagged PDF questions
What does tagged PDF mean?
A tagged PDF contains a structure tree that identifies headings, paragraphs, lists, tables, figures, links, and other content. The tags help screen readers understand the file beyond its visual layout. A tagged PDF still needs testing because tags can be missing, inaccurate, or arranged in the wrong reading order.
Does a tagged PDF meet WCAG?
A tagged PDF does not automatically meet WCAG 2.1 AA. Tags support important requirements, but accessibility also depends on reading order, alternate text, contrast, link text, keyboard use, and form behavior. Check the file with an automated PDF accessibility checker, then perform human review with a screen reader and visual inspection.
How do I know if a PDF is tagged?
You can check for a tag tree in a PDF editor or run an automated PDF accessibility check. A tag tree suggests that the file has structure, but it doesn't prove that the structure is correct. Open the tree and look for headings, paragraphs, lists, tables, and figures. Then test the reading order on complex pages.
Can a scanned PDF be tagged?
A scanned PDF can be tagged after OCR creates a text layer. OCR alone only makes the page searchable. The file still needs headings, reading order, table structure, figure descriptions, and other accessibility work. Scans with poor quality or unclear contrast may also need source-level correction.
Is automatic PDF tagging enough?
Automatic PDF tagging is a useful first pass, but it isn't enough for reliable accessibility. Automatic tools can misread columns, headings, tables, captions, and decorative objects. Review the tag tree, check reading order, listen with a screen reader, and run an automated validator before publishing the file.
Conclusion
A tagged PDF gives assistive technology a map of the document, but the map must be accurate and usable. For a small set, repair each file by hand and test it. For a large backlog, use a repeatable workflow with machine checks plus human review where meaning matters. If you want to test your own files, run the first 100 pages through the Accessibility On Demand™ free trial and review the results against your document needs.
